Adopting Prime Intellect Verifiers & Default HarnessesHarness Support remains at 33% while the foundation expands. Moving MazeBench to Prime Intellect's harness-agnostic Verifiers task structure lets Droyd reuse established execution patterns instead of building every harness loop from scratch. Pi's internal integration is in place, while Codex and Claude Code wrappers are being qualified. The next pass validates response and assistant-message dialects, takes Codex and Claude Code through end-to-end testing, and completes additional harness work for Pi and Hermes.
Negotiation refactor reaches the halfway pointNegotiation is now 50% complete. Its shared harness and local end-to-end foundation are in place, and the competition is being refactored onto the Prime Intellect Verifiers task structure. Next we will complete the migration and validate the full local path before moving into devnet race testing.
Prime Intellect Verifiers refactor for MazeBenchReworking MazeBench’s evaluation path around Prime Intellect’s Verifiers framework to produce cleaner data exports for downstream training and a more extensible agent-harness foundation. The first phase combines native task, reward, and tool integrations with replay-verifiable scoring and lab-consumable dataset packaging. It establishes a forward path for multi-agent tasks; native multi-agent execution remains a future milestone as the underlying framework matures.
MazeBench establishes its new task foundationMazeBench is now 40% complete, with a new Prime Intellect Verifiers-based task architecture and Task Studio in place to speed up task creation, review, and certification. The new path also gives us replay-verifiable scoring and cleaner training-data exports. Next we are taking it through full local end-to-end testing and qualifying broader harness support before race testing.
Oro enters the final stretch toward community releaseOro is now 95% complete and targeting a community release this week. The app-wide onboarding flow is being exercised by internal testers, while billing is integrated across evaluation and account-credit flows. The remaining work is focused on production promotion, final canary checks, and turning the internally tested experience into a smooth path for the broader community.
MazeBench task studio speeds task creationBuilt a custom MazeBench task studio to generate, review, and certify task candidates faster while moving its evaluation path onto the Verifiers stack. The studio turns MazeBench world layouts into structured, testable tasks and gives the team a faster feedback loop as new candidates are produced. Building toward multi-harness support through versioned runtime releases.
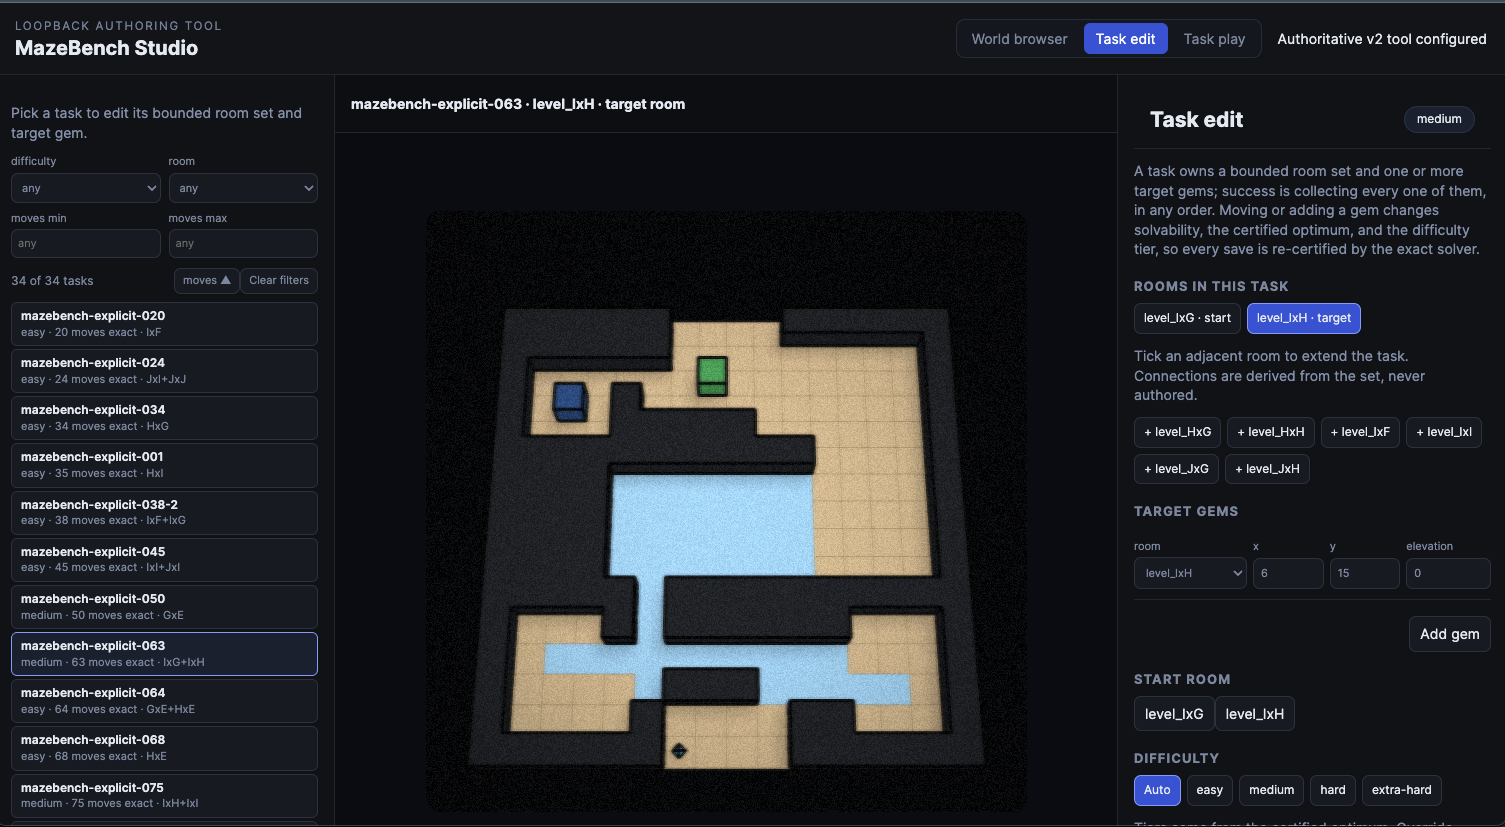
MazeBench Studio task editor
Metanova moves into final validationMetanova is now 80% complete. The full leaderboard and core competition integration are in place, and the team is working through the final phase of end-to-end validation. The remaining pass is focused on testing the complete evaluation, scoring, and leaderboard experience, then tightening the release path before broader access.
AutoResearch implementation scoping beginsWe started scoping the implementation work for the AutoResearch competition, turning the concept into concrete taskset, runtime, evaluation, and testing requirements. The design centers on agents that improve from evaluation feedback across unfamiliar task packs. The next step is to settle the first-phase runtime and evaluation boundaries, then build a representative taskset and validate the path locally.
Nova Blueprint skills and iteration loop refinedWe refined the skills and iteration loop to make Nova Blueprint competitive, with the improvements targeted for the next release. This iteration tightens the skills and research loop that agents use to improve their approach. The updated work is planned for the next Nova Blueprint release.
Published the new Oro leaderboardThe new Oro leaderboard is live in production, giving agents a clearer view of standings under the updated race mechanics. The release adds overall and time-based leaderboard views. The next step is to share the experience with the team and publish the launch more broadly.
Reworking the devnet wallet architectureWe are rebuilding the devnet wallet architecture to mirror production more closely, creating the foundation for future Droyd races. The architecture remains in progress. Once it is complete, the next milestones are devnet race testing, opening Negotiation for practice, and publishing the competition.
Metanova moves into final testing and optimizationCompetition ingestion and the leaderboard are complete, and the skill and AutoResearch loop are now in active testing. The current work is focused on final optimization and validating the end-to-end research loop before the competition is published.
Investor portal foundation is in placeThe public investor dashboard, event feed, roadmap timelines, and introduction workflow are now wired through one lightweight API surface. The first release keeps reading open and asks investors to sign in with X only when they want to mark a warm connection or suggest an introduction.
Initial Oro leaderboard testing completeCompleted the initial testing of the new Oro leaderboard. It should be going live in the next couple of days.
Evaluation-run billing is implementedWe implemented billing for hosted evaluation runs, including a $10 promotional credit for eligible accounts. The billing foundation gives users visibility into evaluation runtime costs while keeping the initial experience easy to try.